
Enterprise AI Pilots Stall on Missing Infrastructure
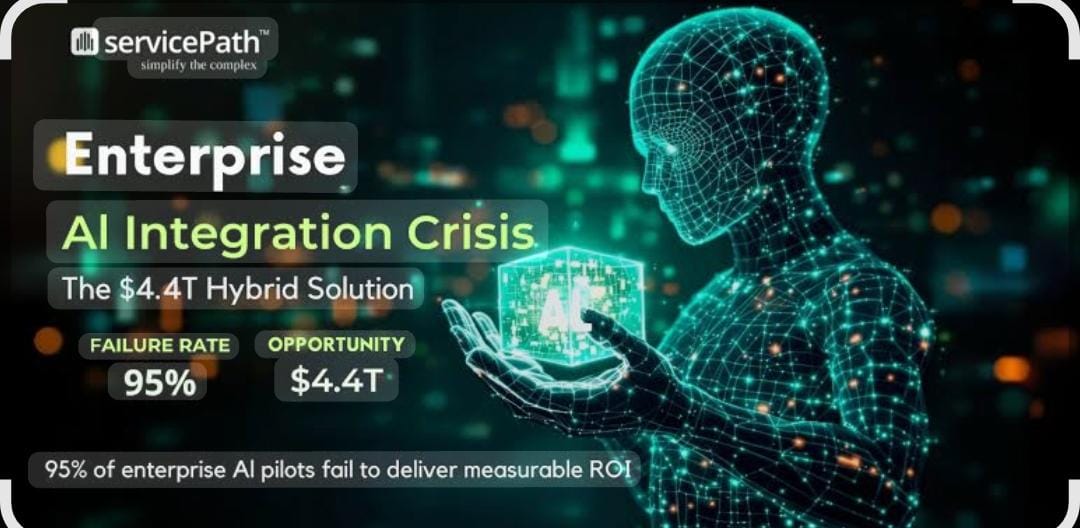
Ninety-five percent of enterprise generative AI pilots produce no measurable financial return, according to MIT’s Project NANDA, which studied more than 300 public AI implementations, 52 interviews, and 153 senior leaders across industries.
The researchers call this “the GenAI Divide.” Just 5% of pilots reach production and generate real value. The rest stall somewhere between demo and deployment. Most of that spending, $30 billion to $40 billion across the enterprises MIT studied, went nowhere near a P&L statement.
MIT’s own explanation for that divide is that the barrier isn’t model quality, infrastructure, or regulation. It’s learning. Most GenAI systems don’t retain feedback, adapt to context, or improve with use. If the system can’t capture how users use its outputs, there is no feedback loop to improve it. AI infrastructure handles that layer by collecting user feedback, logging model responses, and feeding those results back into evaluation and future model updates.
Everyone Adopted AI, But Almost No One Scaled It
Enterprise AI has an adoption problem in reverse. Almost everyone has adopted it. Almost no one has scaled it.
Eighty-eight percent of organizations report using AI in at least one business function, according to McKinsey’s most recent State of AI survey of nearly 2,000 leaders across 105 countries. Only about a third say they’ve begun scaling it across the enterprise. Enterprise AI adoption and enterprise AI impact have become two distinct metrics, and most of the industry is still measuring the former.
Agentic AI shows the same split at a sharper angle. Sixty-two percent of organizations are experimenting with AI agents, McKinsey found, but only 23% are scaling them anywhere, and in any single business function, no more than 10% are scaling agents at all.
Gartner, the research and advisory firm, expects that gap to close quickly on paper, with 40% of enterprise applications incorporating task-specific AI agents by the end of 2026, up from under 5% in 2025. Whether that many pilots survive contact with production is a separate question entirely.
Gartner Says 40% Of Agentic AI Projects Won’t Survive 2027
Gartner’s forecast points to a similar problem to the one MIT identified in its research. The issue isn’t simply whether the underlying model works. Gartner cites escalating costs, unclear business value, and inadequate risk controls as the three main reasons projects get canceled.
“Most agentic AI projects right now are early-stage experiments or proofs of concept that are mostly driven by hype and are often misapplied,” said Anushree Verma, a senior director analyst at Gartner, in the firm’s forecast release.
What Vendors Mean By ‘Agentic AI’
Gartner estimates that only about 130 of the thousands of vendors marketing “agentic AI” products meet its definition. The rest are existing chatbots, assistants, and automation tools repackaged as agents, a practice the firm calls “agent washing.”
“Most of the agentic AI projects we see canceled were never going to survive contact with a real workload,” says David Barlev, founder and CEO of Goji Labs, a Los Angeles firm that works on AI product development alongside custom software builds.
He says teams can build a polished demo. Once people start using it, though, they often don’t have a clear record of where the agent worked and where it failed. That’s a problem when the team has to decide whether the next round of funding is justified.
What An AI Readiness Assessment Checks First
Most teams start an AI project by picking a model. The more useful first step is checking whether the systems around it are ready. Take a support team that wants AI to read incoming tickets and route them to the right department. So before anyone builds the model, there are three things to check:
- Data quality. Start with a few hundred recent support tickets and look at how agents have labeled them. Missing information, duplicate records, or three different labels for the same type of request can all create problems once the data reaches the model.
- The workflow. Follow a ticket from arrival to resolution. Where would the AI hand off its recommendation? If there’s no clear place for that output to go, the team has an integration problem to solve first.
- The infrastructure. Run the feature against the traffic it will see in production, including peak periods and the other systems it needs to call. A laptop demo won’t tell you whether the setup can handle 10,000 tickets a day.
Teams that skip this groundwork can spend six weeks proving an idea, then spend six months rebuilding the systems around it.
Why Evaluation Is Where Most Pilots Break
MLOps (Machine Learning Operations) started out narrow, just deploying a model and keeping it running. Today’s AI systems don’t work that way. An agent might call three other tools mid-task, chain a dozen steps together, and get retrained the following week. The deploy-and-monitor approach doesn’t stretch to cover any of that.
Modern MLOps has grown to cover governance, tracing across multi-step agent workflows, cost and latency monitoring, and evaluation of outputs against real-world edge cases before and after launch.
That last piece, evaluation, is the layer most stalled pilots never build. A model can pass every benchmark in a research paper and still fail in production, because production edge cases look nothing like a benchmark set.
Without a system to catch the gap between benchmark and reality, a team finds out its agent is failing only when an angry customer reports it, without a dashboard ever flagging it first.
Observability Just Became Mandatory
Tracing an agent’s reasoning step by step, flagging when it selects the wrong tool, and scoring output quality automatically used to be a specialty add-on. It’s turning into baseline infrastructure.
Gartner projects that by 2028 LLM observability will account for half of all GenAI deployments, up from the current rate of about 15%. Stalled pilots explain the jump. A failure nobody can see doesn’t get fixed. It gets restarted, which tells a team nothing about what went wrong the first time.
“Most teams reach for a bigger model when a pilot stalls. That’s rarely the actual problem. We’ve seen teams fix six months of stalled output with one dashboard that showed which cases the agent was getting wrong, not a single model upgrade,” says Barlev.
His team’s case isn’t unique. Visibility into failures, not a smarter model, is usually what gets a stalled pilot moving again.
Launch Day Is Only The Beginning
Pilot testing usually works with a fixed set of inputs. Production doesn’t. Once the system is live, users send requests the team never tested, and the volume can change from one week to the next.
AI model deployment brings those unknowns into production, which is why monitoring needs to continue after launch. Teams can track output quality, costs, latency, and the types of requests the system handles, and spot problems as they arise.
A one-time pilot review can’t catch those changes. MIT found that only 5% of AI pilots make it past the demo stage. The other 95% stall somewhere between the demo and actual use.
Monitoring can show when response quality drops, costs climb, or the agent starts failing on requests it handled correctly during the pilot.
What Successful AI Pilots Do Differently
A good pilot has a narrow enough scope to measure something real, with the success metric agreed on before launch.
Evaluation and monitoring belong in the build from the start. McKinsey’s data also show that high-performing organizations are roughly three times more likely to redesign the workflow around the AI system rather than add a model to a process built for human workers.
The same issue shows up in how companies spend their AI budgets. More than half of enterprise AI spending in 2025 went to sales and marketing pilots, which had high executive visibility but, according to MIT’s research, some of the weakest returns. Back-office automation got less funding even though these projects produced stronger results.
Choosing a pilot because it attracts attention makes it harder to judge whether the AI is actually delivering value.
How Better Evaluation Saved An AI Pilot
Motorway runs a UK car marketplace. Up to 8,000 dealers bid on vehicles there every day. The company built an AI agent so dealers could search inventory with plain language instead of digging through manual filters.
It worked most of the time. Tool-selection errors and misread queries put the failure rate around 1 in 8 searches, but the number alone didn’t say which failures actually mattered. Nobody found out until a dealer complained.
Motorway skipped the model upgrade. Working with AWS, they built an evaluation pipeline that scored tool selection, reasoning, and output quality against real dealer queries. Problems got flagged before launch instead of after a complaint. The failure rate dropped to 1 in 50. Detection time dropped too, down to minutes instead of hours.
That’s what turned an AI pilot into a production-ready product here. The same process holds up the next time an agent needs it.
Why Companies Outsource AI Product Development
Scoring tool selection, tracing reasoning, and grading output against real queries is a specialized problem in its own right. And that is distinct from building the AI feature itself.
Internal engineering teams are often strong at product work: interfaces, workflows, and integration with existing systems. Evaluation infrastructure is different. It’s rarely something a general software team has built before, so that’s usually where the gap shows up.
That’s the exact hole AI product development services firms are usually brought in to fill. Not to replace an internal team’s product judgment, but to bring the evaluation, monitoring, and deployment infrastructure that turns a working demo into something that survives contact with real users.
The Numbers Favor Outside Help
MIT’s research found a clear difference in outcomes based on how companies staffed their AI pilots. Pilots that combined internal AI specialists with outside expertise had a 67% success rate. For teams working entirely in-house, the figure was 22%.
That difference fits the pattern running through the rest of the research. Evaluation and deployment need attention from the start, and outside specialists can bring that experience into the project alongside the internal team.
This gives companies a way to track performance, catch problems, and make changes while the pilot is still being developed.
The Work After The Demo
A working demo answers one question: can the model do the task? Production raises a different set of questions. How often does it get the answer right? Where does it fail? What does each failure cost? And how will the team know when performance starts to slip?
The research in this piece points to the same gap. Gartner cites unclear business value and weak risk controls among the reasons agentic AI projects get canceled. MIT found that many AI pilots stall before production because companies struggle to measure how the systems perform in real use. The pilots that do reach production tend to have evaluation, monitoring, and workflow changes built into the project from the start.
AI infrastructure provides the systems needed to log model outputs, track performance, flag failures, and give teams the data they need to improve the system. The demo proves that the model can work. Infrastructure gives the team a way to keep it working once real users get involved.

Leave a Reply