
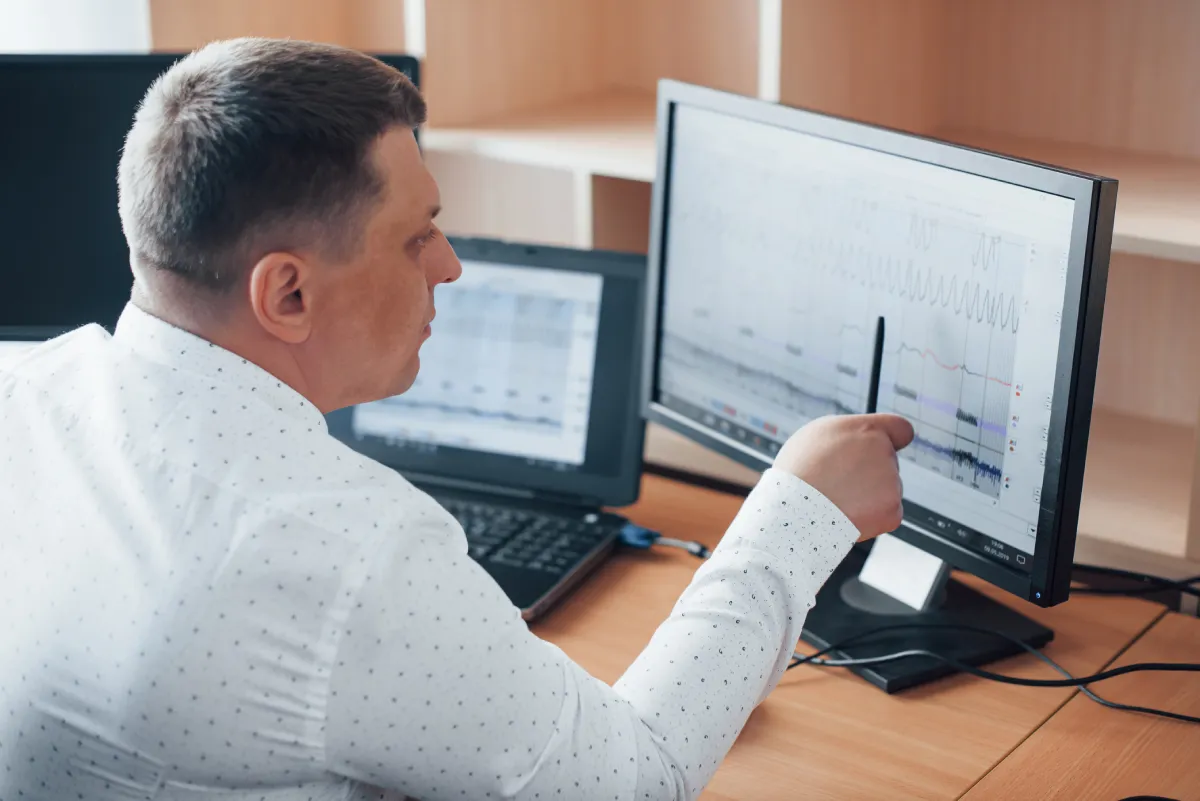
Proactive Monitoring for Modern Data Pipeline Reliability
Reliable data pipelines are the backbone of effective analytics, machine learning, and operational decision-making. As pipelines grow in complexity, static monitoring practices that only react to failures are no longer sufficient. Proactive monitoring anticipates issues, reduces downtime, and preserves trust in the information consumers rely on. This article explores why proactive monitoring matters, the core capabilities you should implement, and practical strategies to build resilient, self-healing data flows.
Why proactive monitoring matters
Reactive monitoring identifies problems after they have already affected downstream users, often forcing teams into frantic firefighting that consumes time and introduces risk. Proactive monitoring shifts the emphasis from incident response to continuous assurance. Instead of waiting for alerts triggered by broken jobs, missing files, or schema mismatches, proactive systems detect subtle deviations from expected behavior. Early detection prevents incorrect reports, failed model training, and costly rollbacks. It also enables teams to prioritize effort: by surfacing issues that carry the highest risk to business outcomes, teams avoid chasing false positives and can allocate resources to fixes that matter.
Beyond reducing outages, proactive monitoring fosters confidence across the organization. When stakeholders know that data quality is actively guarded, they are likelier to trust analytics outputs and automation that depend on those pipelines. Trust in data cultivates faster decision cycles and more experimentation, which drives innovation.
Core components of an effective proactive system
At the center of a proactive monitoring strategy are three interlocking capabilities: health telemetry, intelligent anomaly detection, and automated remediation. Health telemetry captures fine-grained signals across orchestration, extract-transform-load stages, storage, and serving layers. Logs, metrics, lineage records, and schema snapshots create a rich context for understanding pipeline behavior. A telemetry-rich pipeline is like a well-instrumented machine that reveals not only that something is wrong but also where and why.
Intelligent anomaly detection moves beyond static thresholds. By leveraging historical baselines, seasonal patterns, and dependency-aware models, detection systems can differentiate normal variance from meaningful drift. This reduces alert fatigue and surfaces the issues that genuinely require human attention. Contextualizing anomalies with lineage and schema information makes it easier to identify root causes, whether they arise from upstream API changes, delayed data arrivals, or subtle corruption.
Automated remediation closes the loop. Where possible, systems should apply predefined corrective actions such as retrying failed jobs, rolling back problematic schema changes, or quarantining anomalous records for review. Combining automated fixes with human-in-the-loop approvals for higher-risk actions ensures safety while accelerating resolution. The most effective proactive systems present clear, prioritized recommendations to engineers, allowing them to validate and deploy fixes quickly.
Observability and tracing across the pipeline
A modern monitoring approach requires unified observability across disparate tools. Instrumentation must tie together events from message queues, batch aggregations, transformation jobs, and serving endpoints. By mapping lineage and capturing metadata at each transition, teams can trace the propagation of errors and assess downstream impact. This tight coupling of trace data with quality checks enables targeted alerts that reference the exact datasets, timestamps, and transformation steps affected.
To support this, teams should adopt standardized metadata schemas and centralize observability outputs into a queryable store. This allows cross-cutting analysis such as identifying recurring failure modes, measuring mean time to detect versus mean time to repair, and quantifying the economic impact of data incidents. A central observability layer becomes the single pane of glass for both operators and data consumers.
Implementation strategy for scaling monitoring
Start small and iterate. Begin by instrumenting the most critical pipelines—those that feed business metrics or customer-facing systems. Define service level objectives for data freshness, completeness, and correctness. Use these objectives to prioritize monitoring investments. Integrate lightweight checks that validate record counts, null rates, and schema conformance, then layer on more advanced behavioral models as you gain historical data.
Automate discovery and onboarding of new pipelines to avoid monitoring gaps as the environment evolves. Incorporate monitoring into the pipeline development lifecycle so checks are defined and tested alongside code changes. Treat alerts as design artifacts: require ownership, action plans, and postmortem reviews when thresholds are breached. Implementing runbooks tied to specific alert signatures will reduce resolution time and aggregate institutional knowledge for future incidents.
Collaborate closely with downstream consumers. Proactive monitoring is most effective when feedback loops include analysts, product managers, and ML engineers who can validate whether detected anomalies are actionable. Regular reviews of monitoring effectiveness will reveal false positives to tune and blind spots to cover. Transparency in incident reporting builds organizational trust and improves remediation practices over time.
Measuring the impact of proactive monitoring
Quantify the benefits of proactive monitoring through metrics that reflect both technical performance and business outcomes. Track reductions in incident frequency and duration, improvements in pipeline uptime, and decreases in data-related support tickets. Correlate these indicators with business KPIs such as revenue at risk, time-to-insight for analytics teams, and model performance stability. Use these insights to justify further investment in automation, telemetry, and data quality tooling.
Adopting a modern governance approach that leverages Data Observability concepts can accelerate these gains by framing monitoring practices around observability principles: completeness, context, and actionability. Shifting to that mindset helps teams prioritize signals that matter and design systems that recover gracefully.
Proactive monitoring is not a one-time project but an evolving capability. As pipelines expand and new data sources appear, instrumentations, detection models, and automation must adapt. However, the upfront effort in building robust surveillance and remediation mechanisms pays dividends in operational resilience, faster analytics, and stronger trust in data. Organizations that invest in proactive monitoring will find their data pipelines become not just functional, but reliably predictive assets that amplify the value of every dataset.

Leave a Reply